Where quantum research is concentrating, what this week’s modular-memory, error-correction and networking results cost once they are put to use, and the developments worth watching as an investor.
This week’s review covers 103 arXiv papers. Sorted by what each one contributes, 50% are algorithms or software, 40% involve hardware or a device, and 48% are about error correction or verification. Every paper carries at least one of the three themes; 36 carry two and 1 carries all three.
The question running through the strongest papers is what a component-level gain is worth once it is put to use. Four results this week put a price on connecting the parts of a quantum computer: wiring modules together, running error correction on an imperfect chip, linking two qubit technologies, and keeping magic states usable. Two are measured experiments; two are design and resource studies.
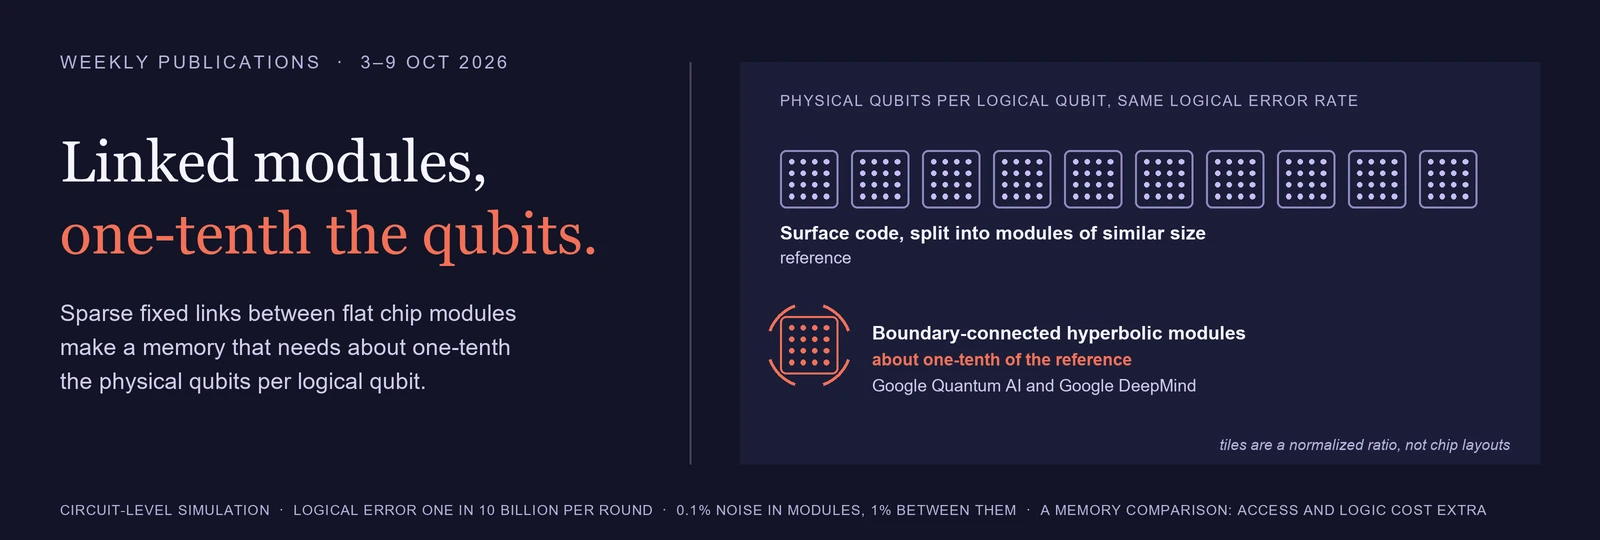
Wiring flat modules together cut simulated memory overhead tenfold.Google Quantum AI and Google DeepMind simulate a memory that needs about one-tenth the physical qubits per logical qubit of a surface code split into similar modules, at a logical error rate of 10−10 per logical qubit per round.
Error correction improved on an imperfect 156-qubit chip.The University of Sydney and IBM excluded weak components and decoded with measured noise on ibm_boston, cutting logical error per round by 23.2% and 18.0% on a 7-by-7 patch. Smaller patches still did better on average.
Two qubit technologies linked at a kilohertz.IonQ and Duke entangled a trapped barium ion with a silicon-vacancy memory in diamond at 1,032 pairs per second and 87.9% fidelity, or 612 per second including readout.
Magic states cost more once they must stay usable.Harvard and MIT estimate roughly five times the expected spacetime volume for one surface-code cultivation setting when acceptance cannot rely on a final measurement that destroys the output.
Where the research connects
Counts from 103 reviewed papers
The overlap between this week’s themes
No publication falls outside these three themes. Areas, including the overlaps, are proportional to publication counts. Each region shows only its combination of labels.
The 41 hardware papers, by platform
Superconducting11
Semiconductor & spin9
Materials & enabling devices6
Networking systems4
Photonics4
Neutral atoms4
Cross-platform or unassigned2
Trapped ions1
04812
Every paper in the hardware & devices theme, counted once under its primary platform, so the bars add up to 41. The theme includes device proposals and simulations as well as experiments. Networking systems are physical links between nodes, such as remote gates, entanglement links and key-distribution equipment.
Bars use a common scale from 0 to 12 papers.
The themes are this review’s own classification, read from each paper’s title and abstract, and they are tags rather than categories: 36 papers carry exactly two of them and 1 carries all three. No paper carries none. The three theme names match earlier weeks, but this week’s labels were assigned afresh, so the shares are not a like-for-like comparison with previous reviews. Papers are assigned to the week by first public arXiv availability: the 3 October 00:00 to 10 October 00:00 Asia/Jerusalem window, which holds the arXiv listings of 5 to 9 October.
Where the system cost becomes visible
Each of the four lead results connects a component to the machine around it, and each comes with an explicit baseline. That makes them useful for judging scaling claims: a gain only counts once it is measured against what the next step in the computer has to pay.
The modular idea had company this week. A Canadian group optimized finite hyperbolic surface codes, doubling code distance at fixed qubit count, and partitioned them into bounded planar modules; tripling the error of long-range gates lowered the estimated thresholds only mildly. On magic states, a single-shot factory design for high-rate qLDPC codes reports CCZ states at logical error rates as low as 10−9 with 10 to 40 times lower space-time cost than state-of-the-art methods, laid out for reconfigurable neutral-atom machines. A symmetry- and AI-assisted search found 564 new distillation factories, and a new simulation method makes a broad class of non-Clifford error-correction circuits, including distillation and cultivation, classically simulable in polynomial time, so costs like these can be checked rather than assumed.
Links between nodes
IonQ’s ion-to-diamond link was one of several networking results. A Swiss team implemented an arbitrary-phase entangling gate and remote single-shot readout between two dilution refrigerators joined by a 30-meter cryogenic link. In quantum communication, a measurement-device-independent key-distribution experiment reported secure key distribution over about 303 km in the asymptotic analysis and 253.56 km with finite-key effects, while accounting for flawed state preparation, and an international team tested key distribution with entanglement-swapped photons from a quantum-dot source, an elementary step toward repeaters.
Imperfect hardware, managed
The IBM experiment fits a wider pattern of papers that treat device unevenness as something to be managed rather than eliminated. An error-attribution method identifies the components that matter most for logical failure: halving the noise on the 5 to 7% of components it selects cut logical error rates by roughly 15 to 25% in simulation, about twice the effect of the same fix applied at random. Calibration rules derived on a 66-qubit superconducting processor halved the mean single-qubit error on one with 337 active qubits, from 0.023 to 0.011. In silicon, exchange-only control of up to 48 electron spins was benchmarked at an effective error of 3×10⁻⁴ per exchange, including the complete control sequence.
Software can reduce the demand too
Danial Motlagh at Xanadu tackles the resource budget from the demand side. His QROM construction loads classical table data into a quantum computation using dense encoding and sequential bit packets. Dense encoding doubles the table entries handled per pass with the same borrowed workspace qubits, which are restored afterward. It halves the dominant Toffoli-gate cost of the previous sequential construction, which works out to about 3.9 times lower dominant cost than the SelectSwap method for large tables of 32-bit entries with limited workspace. Fewer expensive operations ease the burden on a fault-tolerant machine, though the saving to a whole program depends on the workload.
Resource estimates themselves came under scrutiny. One paper built an error-rate distribution from five large-array devices, adding an assumed 1.3-fold penalty for deployed hardware. The resulting median is about 4×10⁻³, rather than the conventional 10−3. In its analytic surface-code model, the 90% interval for physical qubits spans a factor of about forty. For RSA-2048, the median is about 4.6 times the conventional point estimate.
The research footprint
Countries and regions represented in the review
A global view of participation
Hover, tap, or choose a country or region.
United States42reviewed publications
Reviewed publications
012.52537.550
Not represented in this review
Affiliation locations; a cross-border collaboration can contribute to several countries. Country or region information is available for 92 of 103 reviewed publications. Map: Natural Earth.
Affiliations were located for 92 of 103 papers from explicit addresses in each preprint, 3 of them only partly. That gives 142 paper-country appearances across 27 countries and territories. Gray means no author affiliation in that country was verified for this selection. A paper with authors in several countries contributes to each of them. Hong Kong is shown separately.
The United States leads with 42 papers, ahead of Germany with 13 and Japan and the United Kingdom with 8 each. Company-linked work in the selection comes from US teams at Google, IBM and IonQ, with Australian, Danish, Swiss and South Korean affiliations on IBM’s experiment. Google’s paper lists its affiliations without addresses, so by this review’s rule it does not count toward the map.
Google Quantum AI and Google DeepMind, with an MIT collaborator
Wiring flat modules into a tenfold leaner memory
Small planar chips are joined by sparse, fixed connections between their boundaries, so the wiring as a whole forms a closed hyperbolic surface while interactions inside each module stay local. In circuit-level simulations, a modular hyperbolic surface code needs about one-tenth the physical qubits per logical qubit of a surface code split into modules of similar size, at a logical error rate of 10−10 per logical qubit per round. Both counts include measurement qubits. The noise model uses 0.1% error inside modules and inter-module gates ten times noisier, at 1%. The authors project savings above 30-fold for larger color-code versions, a projection rather than a simulated result.
Circuit-level simulation
The wiring changes the memory cost
Normalized comparison, not actual qubit counts. Both include measurement qubits. The diagram shows the simulated ≈10-fold saving; the separate >30-fold color-code projection is not plotted. Memory access adds hardware and time. Paper ↗
Why it matters. Modular construction is usually treated as a cost; here the wiring between modules becomes the source of the saving, and it tolerates noisy links. It is a memory comparison: reaching the stored qubits uses added extractor hardware and time. The practical test is how much of the tenfold saving survives once information moves through the rest of the computer.
University of Sydney and IBM Quantum, with EPFL and Sungkyunkwan University
Error correction that works around a chip’s weak spots
On ibm_boston, a 156-qubit Heron processor with heavy-hex connectivity, the team runs a dynamic compass code across the whole chip. It redesigns the measurement schedule to exclude underperforming qubits and couplers, and decodes with measured noise information. On a 7-by-7 memory patch, before any leakage-based run rejection, logical error per round falls 23.2% for Z memory and 18.0% for X memory against decoding with the reported noise, even though excluding two defects lowers the patch’s code distance from 7 to 5. Lattice surgery between patches reaches a Bell-state fidelity lower bound of 97.6%, after pre-selection removes 86.7% of attempts and post-selection keeps 27% of the rest: about 3.6% of the starting attempts.
Measured experiment
Change the checks. Calibrate the decoder.
The workflow is conceptual. Bars normalize reported-noise decoding without defect exclusion to 100. Combining defect exclusion with measured-noise decoding gives 76.8 for Z memory and 82.0 for X memory. These are relative errors, not absolute error rates. Smaller patches still perform better on average. Paper ↗
Why it matters. Real chips are uneven, and this is a practical way to get value from imperfect hardware: extra qubits help only when the protection they add outweighs the faults they bring. It does not yet show memory improving as codes grow. Smaller 3-by-3 patches still perform better on average, because many of them can avoid every weak component. The high Bell fidelity and the low yield belong together.
A single trapped barium ion emits a photon that is converted from 493.5 nm to 737 nm, and from polarization to time-bin encoding, then reflected off a silicon-vacancy center in a diamond nanophotonic cavity. One detected photon heralds entanglement between the ion and the diamond memory. The link produces 1,032 entangled pairs per second at 87.9% Bell-state fidelity, about four times the 250 pairs per second of the fastest published link between two trapped ions. That rate counts initialization, repeated attempts and resets, and stops when readout begins; including the readout used to verify the pairs, it is 612 per second.
Measured experiment
Convert the photon. Then count the full cycle.
The optical path is schematic. The two bars count the same link with different timing boundaries; the 612 pairs/s rate includes the readout used to verify the entanglement. Neither rate measures a distributed computation. Paper ↗
Why it matters. IonQ showed the 1 kHz figure at its September Investor Day as a forthcoming study; this paper supplies the evidence behind it. For IonQ’s networking plans, the step that matters is a working interface between two different qubit technologies. Neither rate yet measures a distributed computation: processor-to-processor logic will need enough entanglement, at high enough fidelity, to be consumed by error-corrected operations.
No company author affiliation · QuEra Computing among the funders
Harvard University and MIT
The real price of a usable magic state
Magic states supply the operations that make fault-tolerant computing universal, and cultivation is a promising low-overhead way to make them. Earlier cost estimates decided which attempts to accept using a noiseless final measurement that would destroy the output. The authors’ Caliper method, a fast soft-output decoder, decides using only the error checks available before that point. For one surface-code setting targeting a logical error of 2 in a million, the cheapest escape stage studied is roughly five times larger than in the earlier estimate, which the authors translate into roughly five times the expected spacetime volume for the whole protocol. The simulations use Y states as a tractable stand-in for T states, at 0.1% physical error.
Why it matters. Factory budgets have to be priced per accepted magic state that can still be used, not per state that passed a test that destroyed it. The multiplier depends on the protocol and target: for a color-code setting at 10−9, the paper finds about 3.7 times. Caliper’s per-shot decoding time is within a factor of two of the earlier method’s, but on superconducting hardware either may need FPGA-class acceleration.
The next useful evidence will connect each improvement to the operation that follows it. For modular memories, that means logical operations and memory access costed on the same footing as storage. For IBM’s approach, it means memory that improves as patches grow on a full, uneven chip. For IonQ’s link, it means entanglement consumed by logical operations between processors, at a rate and fidelity those operations can use.
For magic states, I would look for an exact T-state calculation under the usable-output constraint, and decoders fast enough that factories do not wait on them. For investors, the test of a scaling claim is concrete: look for gains that survive a consistent accounting of qubits, time, accepted outputs and the classical work that supports them.